Dataviz caveat
The issue with stacking
What is stacking
Stacking is a process where a chart is broken up across more than one categoric variables which make up the whole. Each item of the categoric variable is represented by a shaded area. These areas are stacked on top of one another.
Here is an example with a stacked area chart. It shows the evolution of baby name occurence in the US between 1880 and 2015. Six first names are represented on top of one another.
Show codeHide code
# Libraries
library(tidyverse)
library(babynames)
library(streamgraph)
library(viridis)
library(hrbrthemes)
library(plotly)

# Load dataset from github
data <- babynames %>%
  filter(name %in% c("Amanda", "Jessica",    "Patricia", "Deborah",   "Dorothy",  "Helen")) %>%
  filter(sex=="F")

# Plot
p <- data %>%
  ggplot( aes(x=year, y=n, fill=name, text=name)) +
    geom_area( ) +
    scale_fill_viridis(discrete = TRUE) +
    theme(legend.position="none") +
    ggtitle("Popularity of American names in the previous 30 years") +
    theme_ipsum() +
    theme(legend.position="none")
ggplotly(p, tooltip="text")Note: This graphic is interactive: hover an area to know the underlying name.
Stacking is a common practice in dataviz. It occurs on three main types of graphic that are highly related: area charts, barplots and streamcharts:
Heaven or Hell?
The efficiency of stacked area graph is discussed and it must be used with care. To put it in a nutshell:
stacked graphs are
appropriateto study theevolution of the wholeand therelative proportionsof each group. Indeed, the top of the areas allows to visualize how the whole behaves, like for a classic area chart. In the previous graphic, it is easy to see that in 1920, Helen and Dorothy were common names but the 4 other names barely existed.however they are
not appropriateto study theevolution of eachindividual group. This is due to 2 main reasons. First, all groups except the bottom one do not have a flatbaseline, so it is very hard to read their values at each time stamp.
Example: mental arithmetic
In the previous graphic, try to find out how many times the name Dorothy was given in 1920.
It is not trivial to find it out using the previous chart. You have to mentally do 75000 - 37000 which is hard. If you want to convey a message efficiently, you don’t want the audience to perform mental arithmetic.
Example: optical illusion.
Important note: this section is inspired from this post by Dr. Drang.
Dr Drang gives this nice example. Consider the graphic below, and try to visualize how the 3 categories evolved on the period:
Show codeHide code
# create dummy data
don <- data.frame(
  x = rep(seq(2000,2005), 3),
  value = c(  75, 73, 68, 57, 36, 0, 15, 16, 17, 18, 19, 20, 10, 11, 15, 25, 45, 80),
  group = rep(c("A", "B", "C"), each=6)
)

#plot
don %>%
  ggplot( aes(x=x, y=value, fill=group)) +
    geom_area( ) +
    scale_fill_viridis(discrete = TRUE) +
    theme(legend.position="none") +
    theme_ipsum() +
    theme(legend.position="none")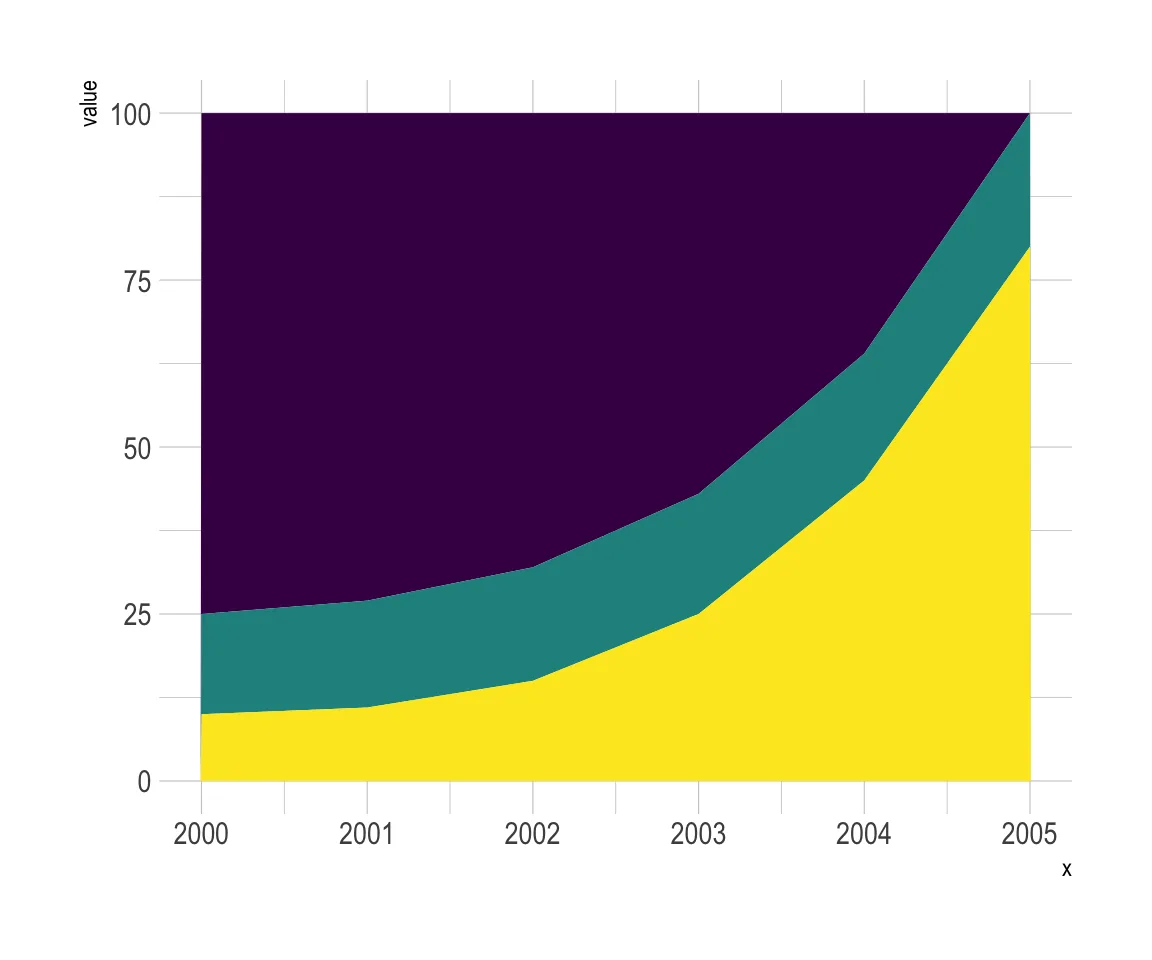
It looks obvious that the yellow category increased, the purple decreased, and the green… is harder to read. At a first glance it looks like it is slightly decreasing I would say.
Now let’s plot just the green group to find out:
Show codeHide code
#plot
don %>%
filter(group=="B") %>%
ggplot( aes(x=x, y=value, fill=group)) +
geom_area( fill="#22908C") +
theme(legend.position="none") +
theme_ipsum() +
theme(legend.position="none")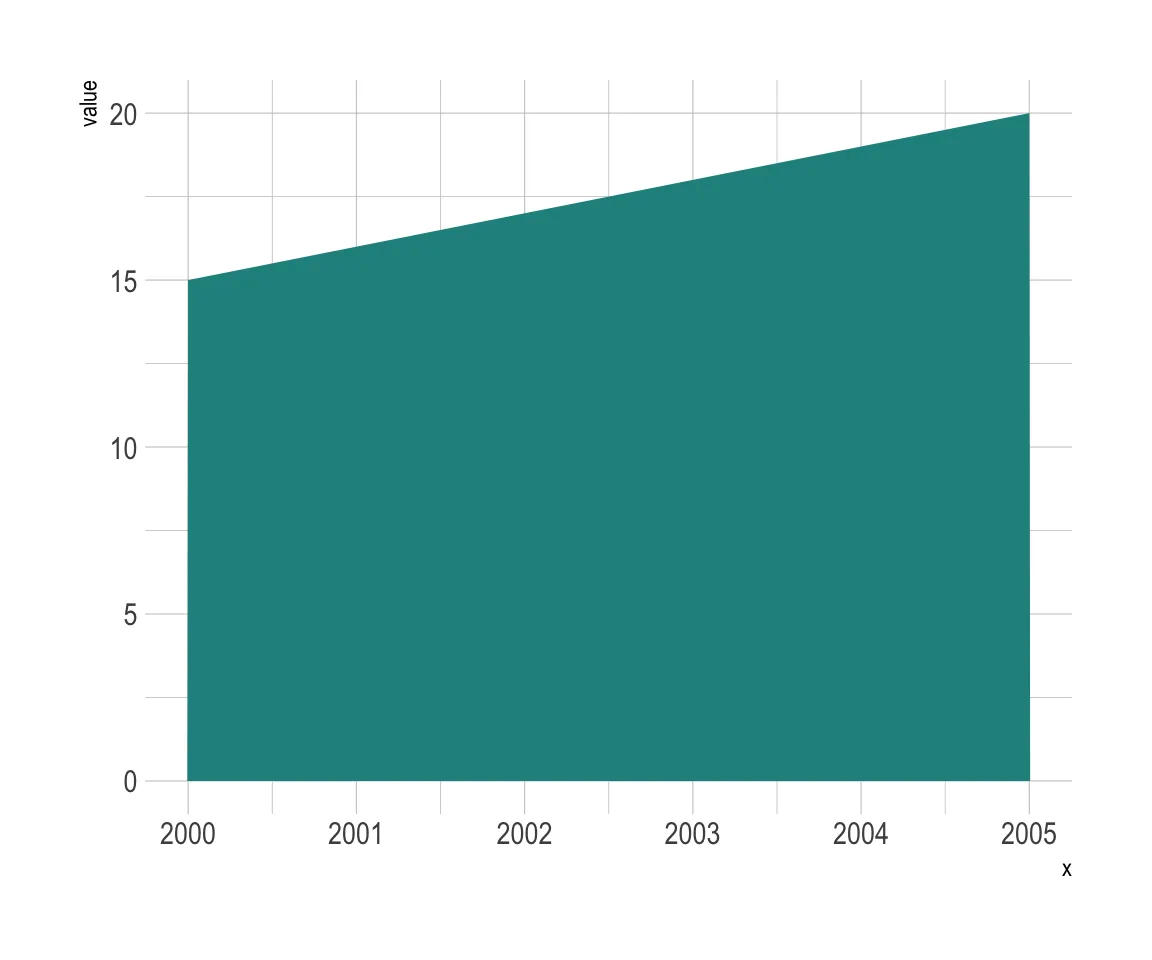 It looks like we were quite
wrong. This is due to an optical illusion. The human eye is not performant to assess that kind a visual patterns, and this is why it must be avoided.
Workaround
If you have just a few categories, I would suggest to build a line chart. Here it is easy to follow a category and understand how it evolved accurately.
Show codeHide code
data %>%
  ggplot( aes(x=year, y=n, group=name, color=name)) +
    geom_line() +
    scale_color_viridis(discrete = TRUE) +
    theme(legend.position="none") +
    ggtitle("Popularity of American names in the previous 30 years") +
    theme_ipsum()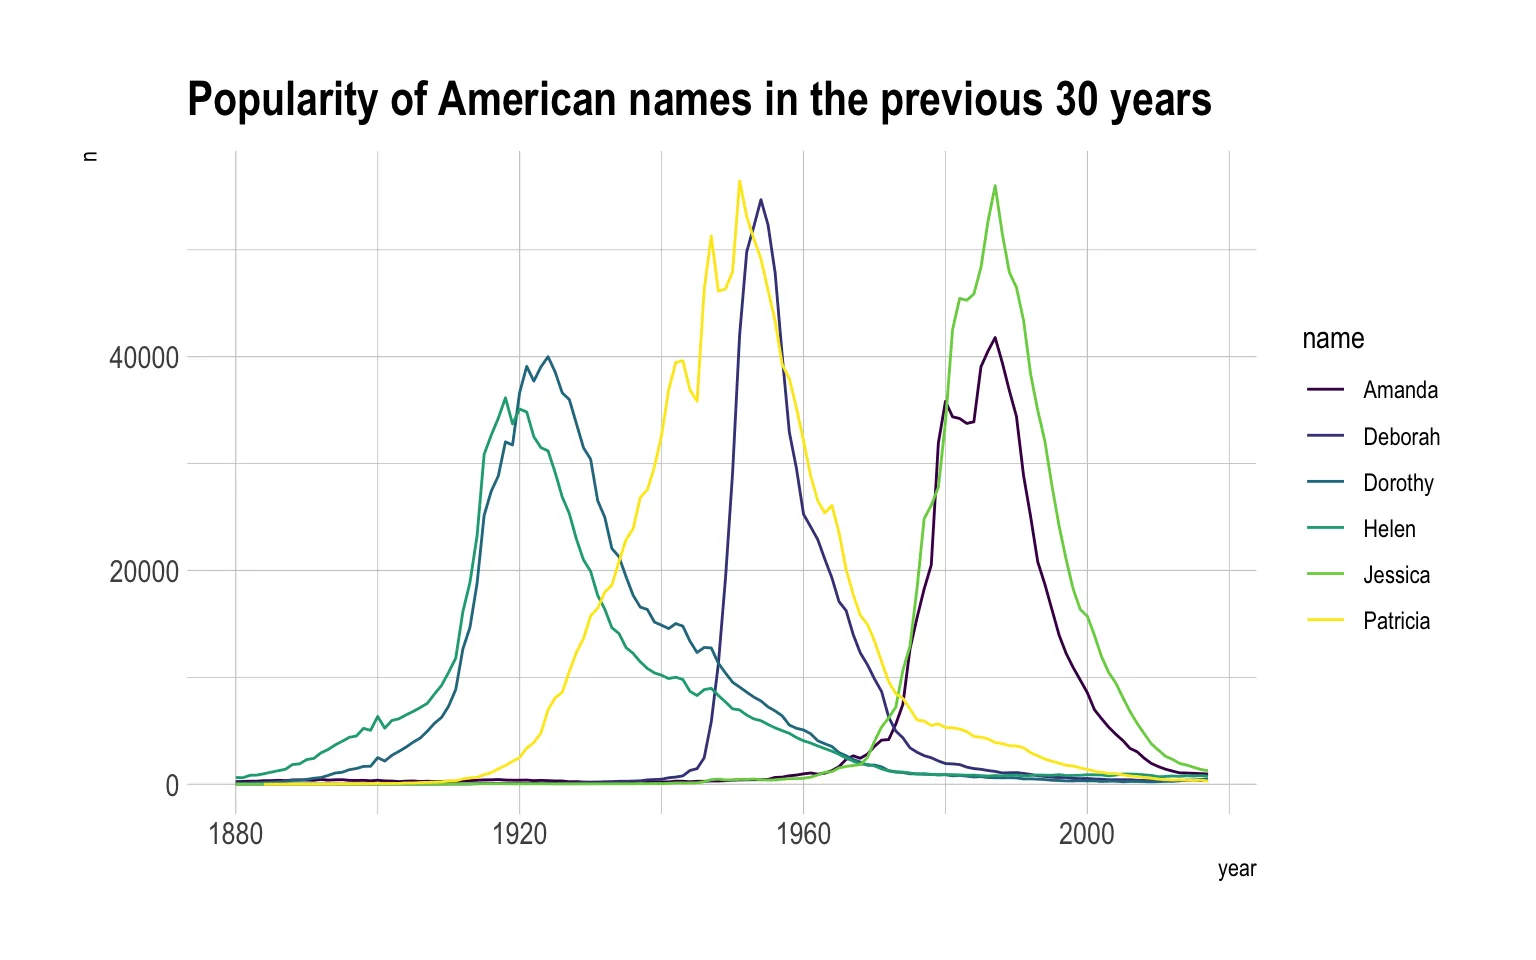
However, this solution is not suitable if you have many categories. Indeed, it would result in a spaghetti chart that is very hard to read. You can read more about this here.
Instead I would suggest to use `small multiple: here each category has its own section in the graphic. It makes easy to understand the pattern of each category.
Show codeHide code
data %>%
  ggplot( aes(x=year, y=n, group=name, fill=name)) +
    geom_area() +
    scale_fill_viridis(discrete = TRUE) +
    theme(legend.position="none") +
    ggtitle("Popularity of American names in the previous 30 years") +
    theme_ipsum() +
    theme(
      legend.position="none",
      panel.spacing = unit(0.1, "lines"),
      strip.text.x = element_text(size = 8)
    ) +
    facet_wrap(~name, scale="free_y")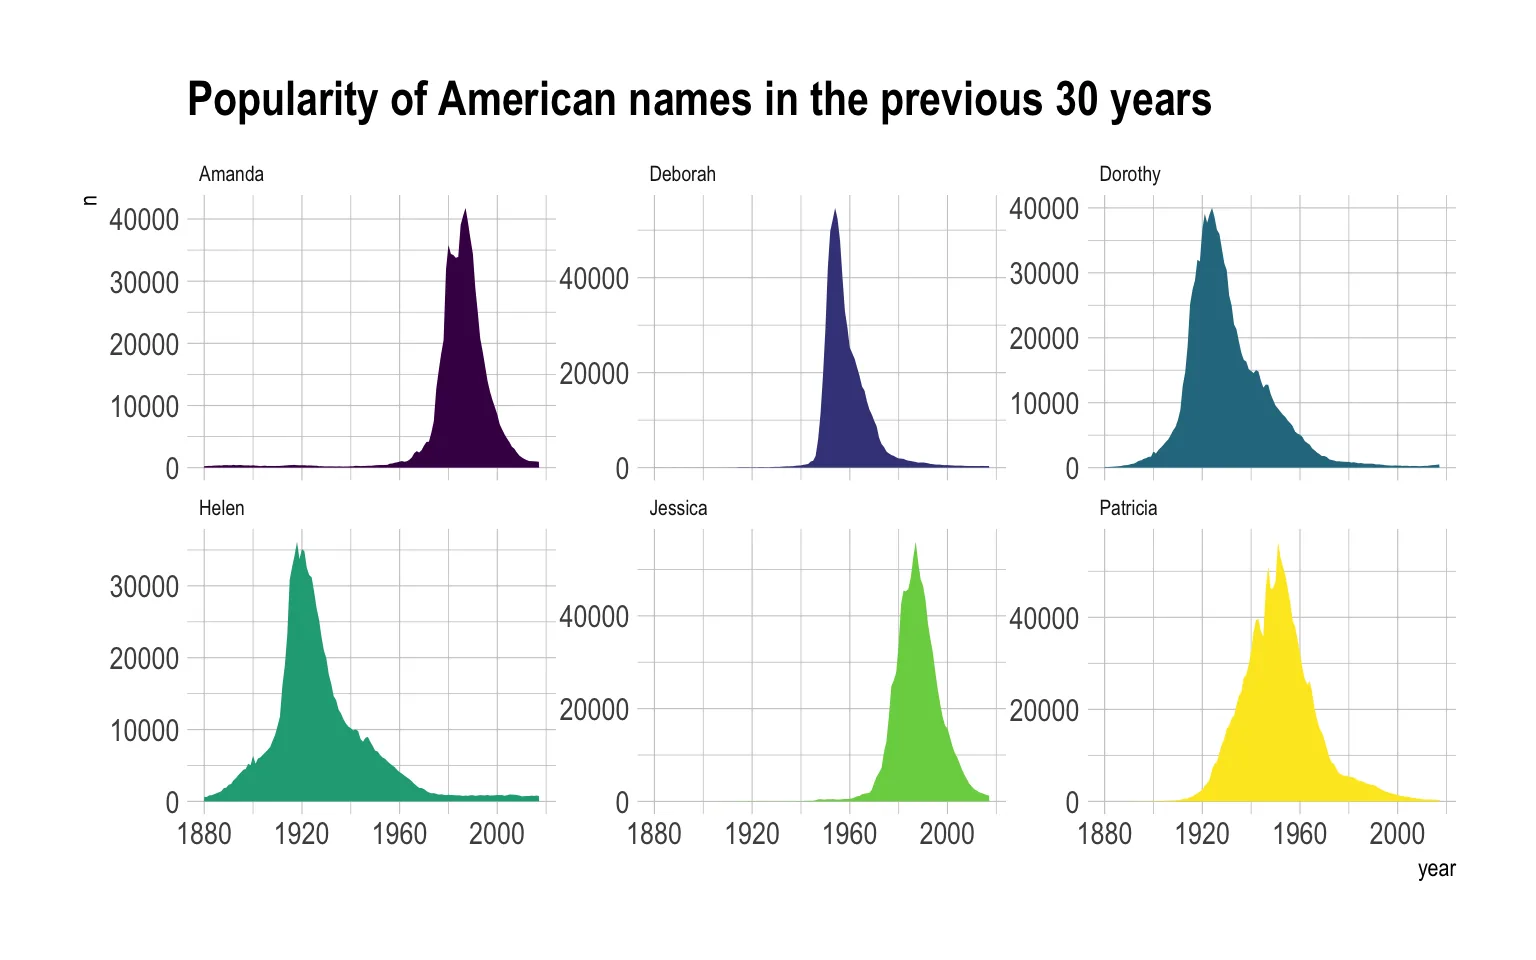
Going further
- Stacked Area Graphs Are Not Your Friend by Everyday analytics
- Quantitative Displays for Combining Time-Series and Part-to-Whole Relationships by Stephen Few
- I hate stacked area charts by Dr Drang