Dataviz caveat
Too many distributions
Comparing the distributions of several numeric variables is a common task in dataviz. The distribution of a variable can be represented using a histogram or a density chart, and it is very tempting to represent many distributions on the same axis.
Here is an example showing how people perceive probability vocabulary. On the /r/samplesize thread of reddit, questions like What probability would you assign to the phrase “Highly likely” were asked. Here is the distribution of the score given by people to each question:
Show codeHide code
#library
library(tidyverse)
library(hrbrthemes)
library(viridis)
library(patchwork)


# Load dataset from github
data <- read.table("https://raw.githubusercontent.com/zonination/perceptions/master/probly.csv", header=TRUE, sep=",")
data <- data %>%
  gather(key="text", value="value") %>%
  mutate(text = gsub("\\.", " ",text)) %>%
  mutate(value = round(as.numeric(value),0))

# A dataframe for annotations
annot <- data.frame(
  text = c("Almost No Chance", "About Even", "Probable", "Almost Certainly"),
  x = c(5, 53, 65, 79),
  y = c(0.15, 0.4, 0.06, 0.1)
)

# Plot
data %>%
  filter(text %in% c("Almost No Chance", "About Even", "Probable", "Almost Certainly")) %>%
  mutate(text = fct_reorder(text, value)) %>%
  ggplot( aes(x=value, color=text, fill=text)) +
    geom_density(alpha=0.6) +
    scale_fill_viridis(discrete=TRUE) +
    scale_color_viridis(discrete=TRUE) +
    geom_text( data=annot, aes(x=x, y=y, label=text, color=text), hjust=0, size=4.5) +
    theme_ipsum() +
    theme(
      legend.position="none",
      panel.spacing = unit(0.1, "lines"),
      strip.text.x = element_text(size = 8)
    ) +
    xlab("") +
    ylab("Assigned Probability (%)")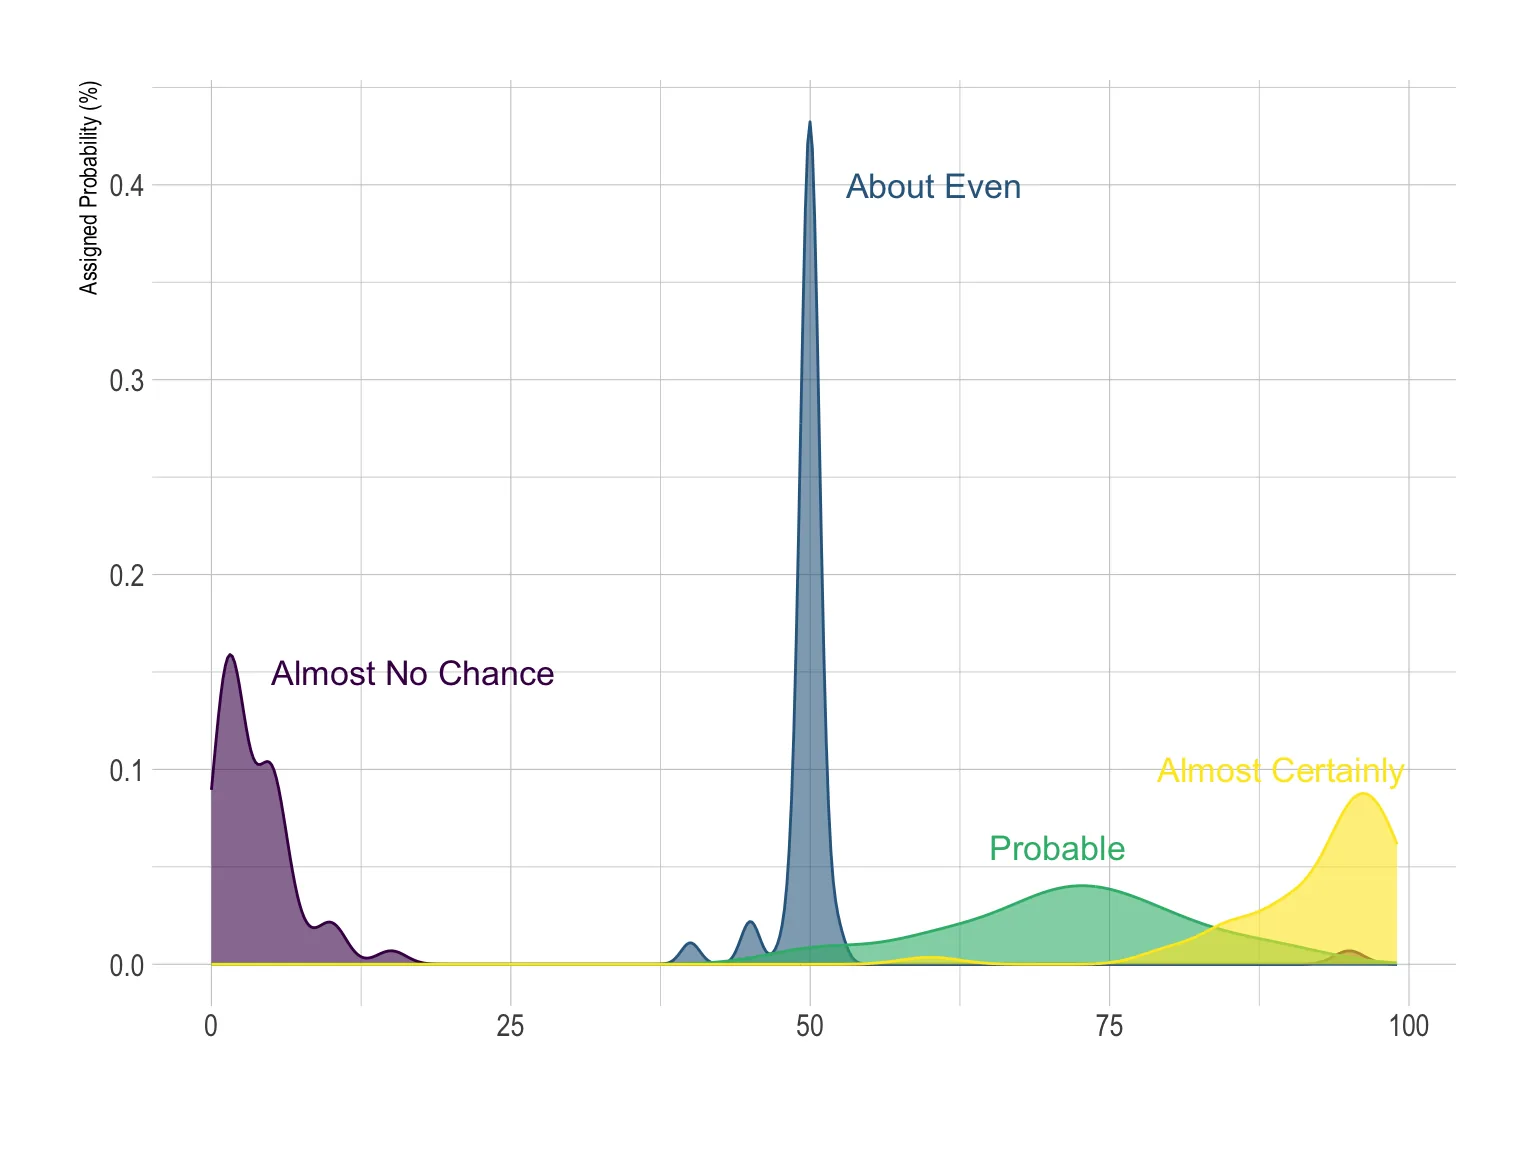
In this case, the figure is quite neat. People give a probability between 0 and 20% for the sentence “Almost No chance”, and between 75 and 100% for “Almost Certainly”. Let’s check what happens with more groups:
Show codeHide code
# Plot
data %>%
  mutate(text = fct_reorder(text, value)) %>%
  ggplot( aes(x=value, color=text, fill=text)) +
    geom_density(alpha=0.6) +
    scale_fill_viridis(discrete=TRUE) +
    scale_color_viridis(discrete=TRUE) +
    theme_ipsum() +
    theme(
      panel.spacing = unit(0.1, "lines"),
      strip.text.x = element_text(size = 8)
    ) +
    xlab("") +
    ylab("Assigned Probability (%)")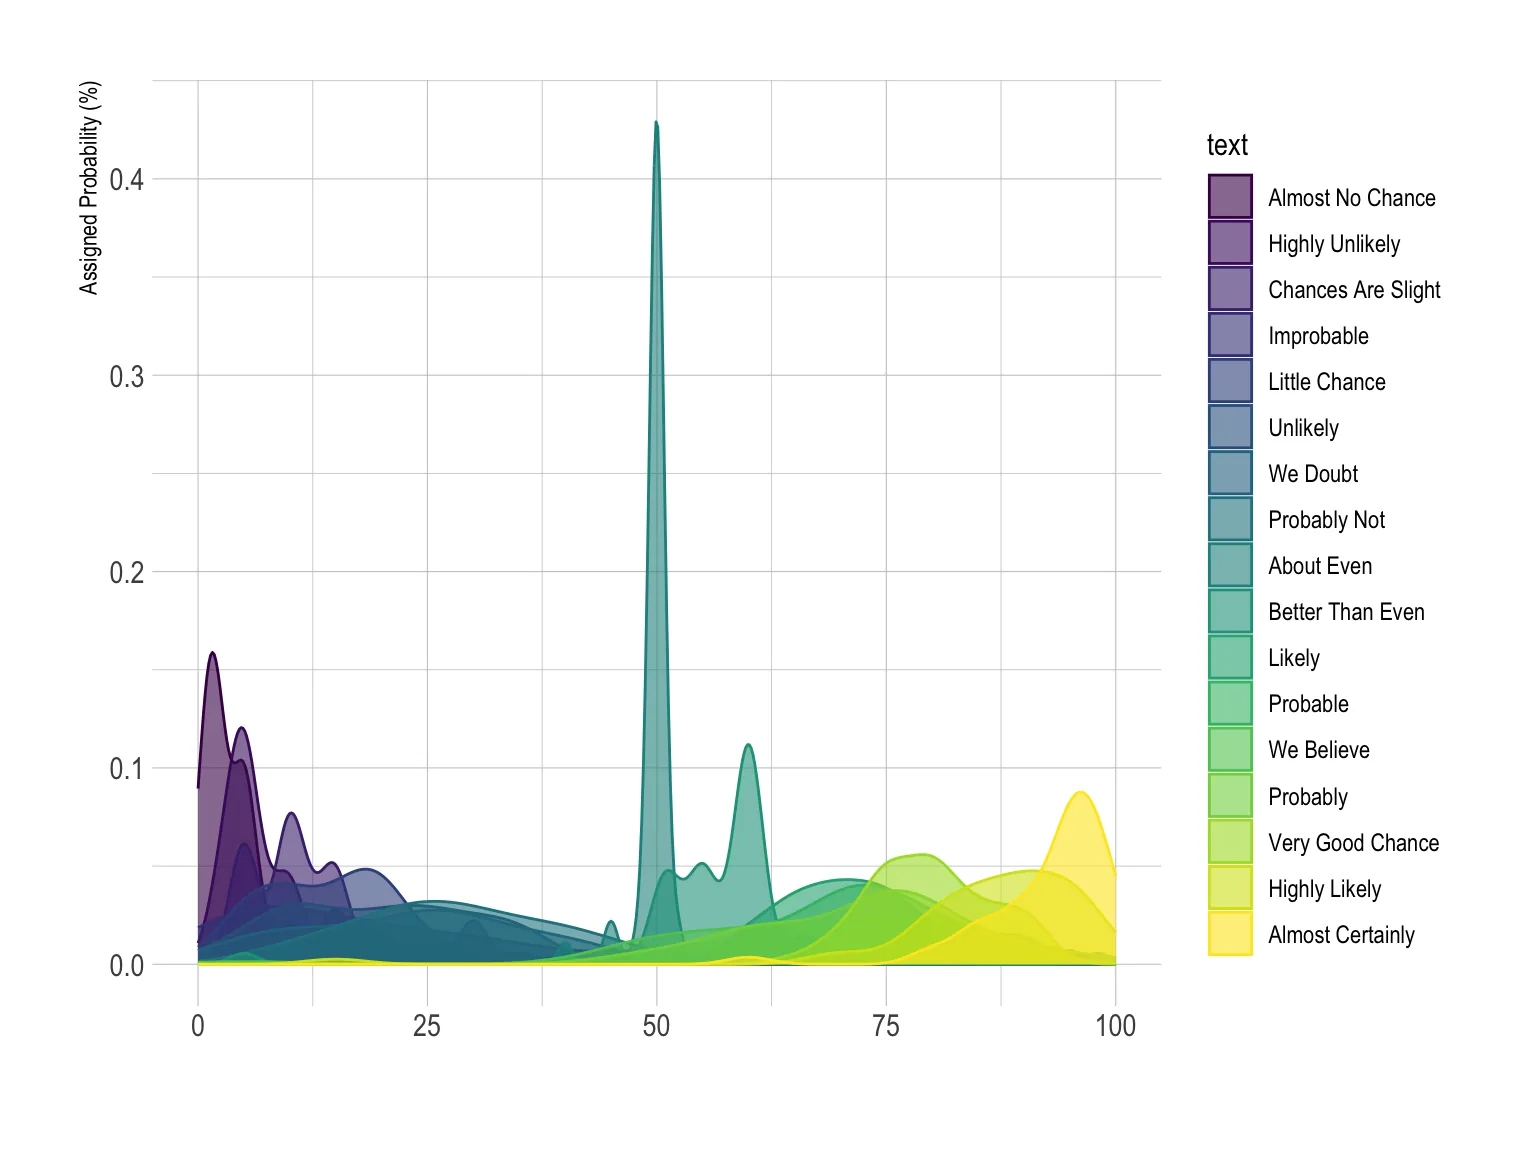
Now the figure is way too cluttered and it is impossible to distinguish groups: there are too many distributions represented on the same graphic. How to avoid that?
Workaround
Several workarounds exist and are presented in detail in this dedicated page. Here is just an overview of the possibilities:
Show codeHide code
data %>%
  mutate(text = fct_reorder(text, value)) %>%
  ggplot( aes(x=text, y=value, fill=text)) +
    geom_boxplot() +
    geom_jitter(color="grey", alpha=0.3, size=0.9) +
    scale_fill_viridis(discrete=TRUE) +
    theme_ipsum() +
    theme(
      legend.position="none"
    ) +
    coord_flip() +
    xlab("") +
    ylab("Assigned Probability (%)")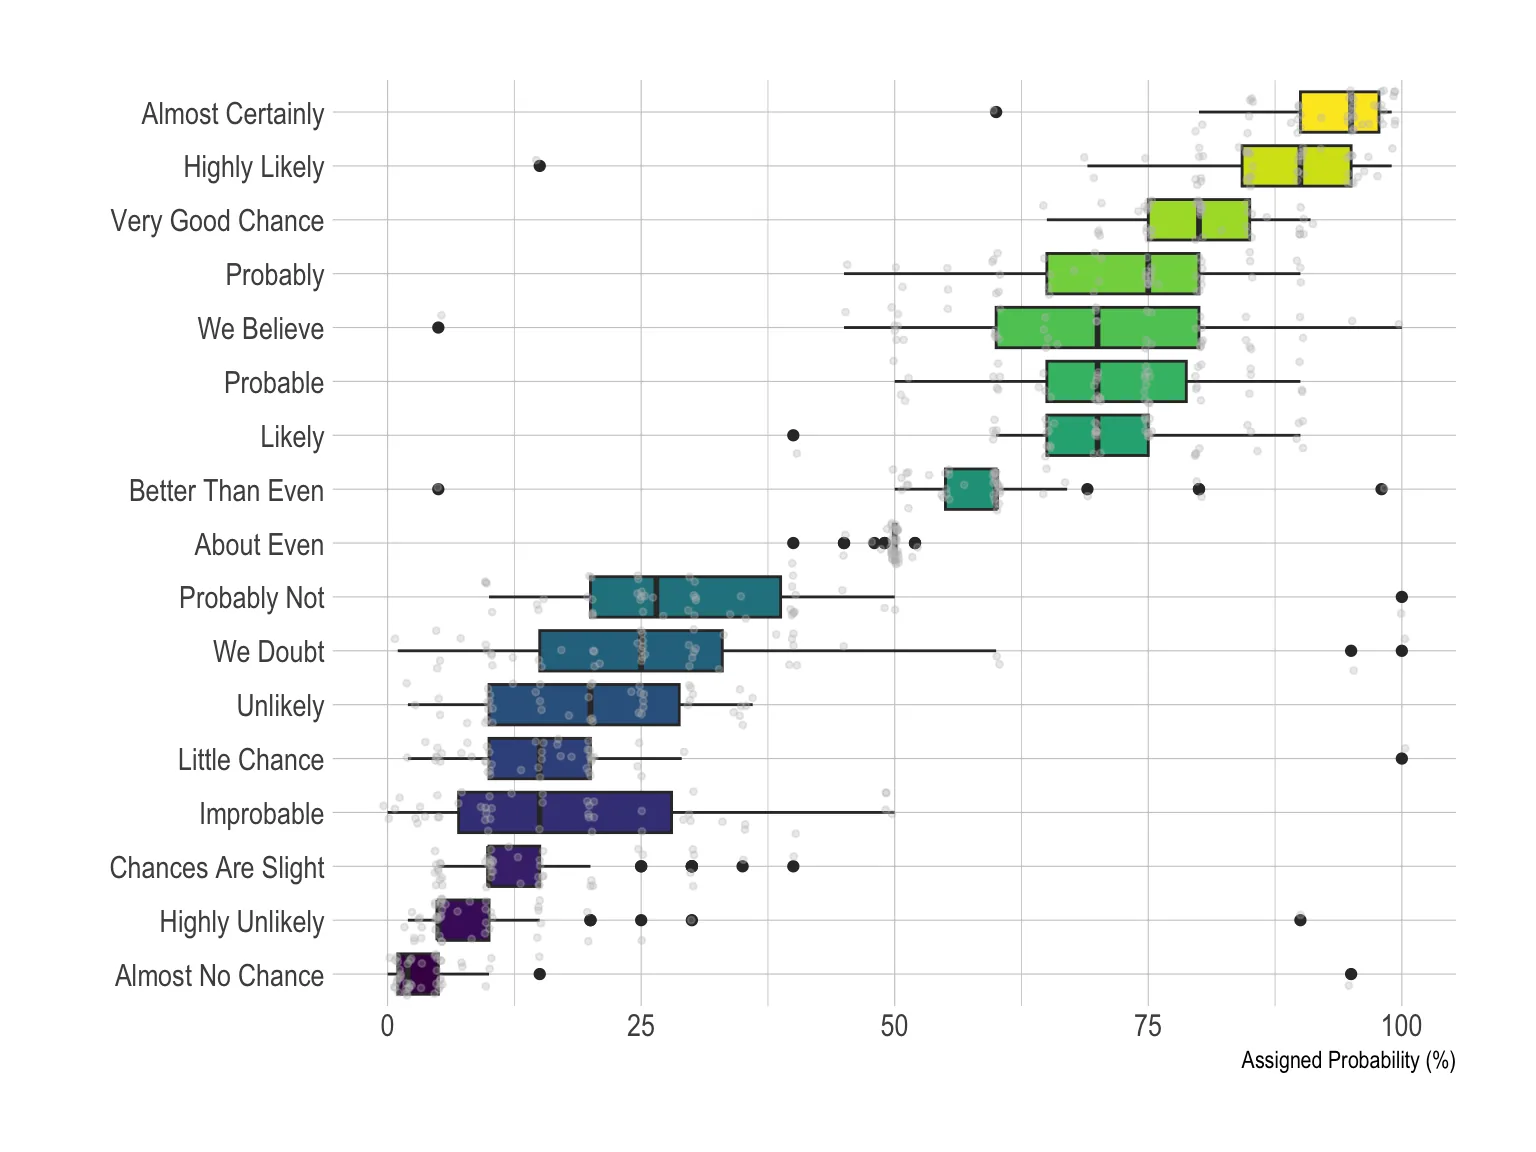
Violin
Show codeHide code
data %>%
  mutate(text = fct_reorder(text, value)) %>%
  ggplot( aes(x=text, y=value, fill=text, color=text)) +
    geom_violin(width=2.1, size=0.2) +
    scale_fill_viridis(discrete=TRUE) +
    scale_color_viridis(discrete=TRUE) +
    theme_ipsum() +
    theme(
      legend.position="none"
    ) +
    coord_flip() +
    xlab("") +
    ylab("Assigned Probability (%)")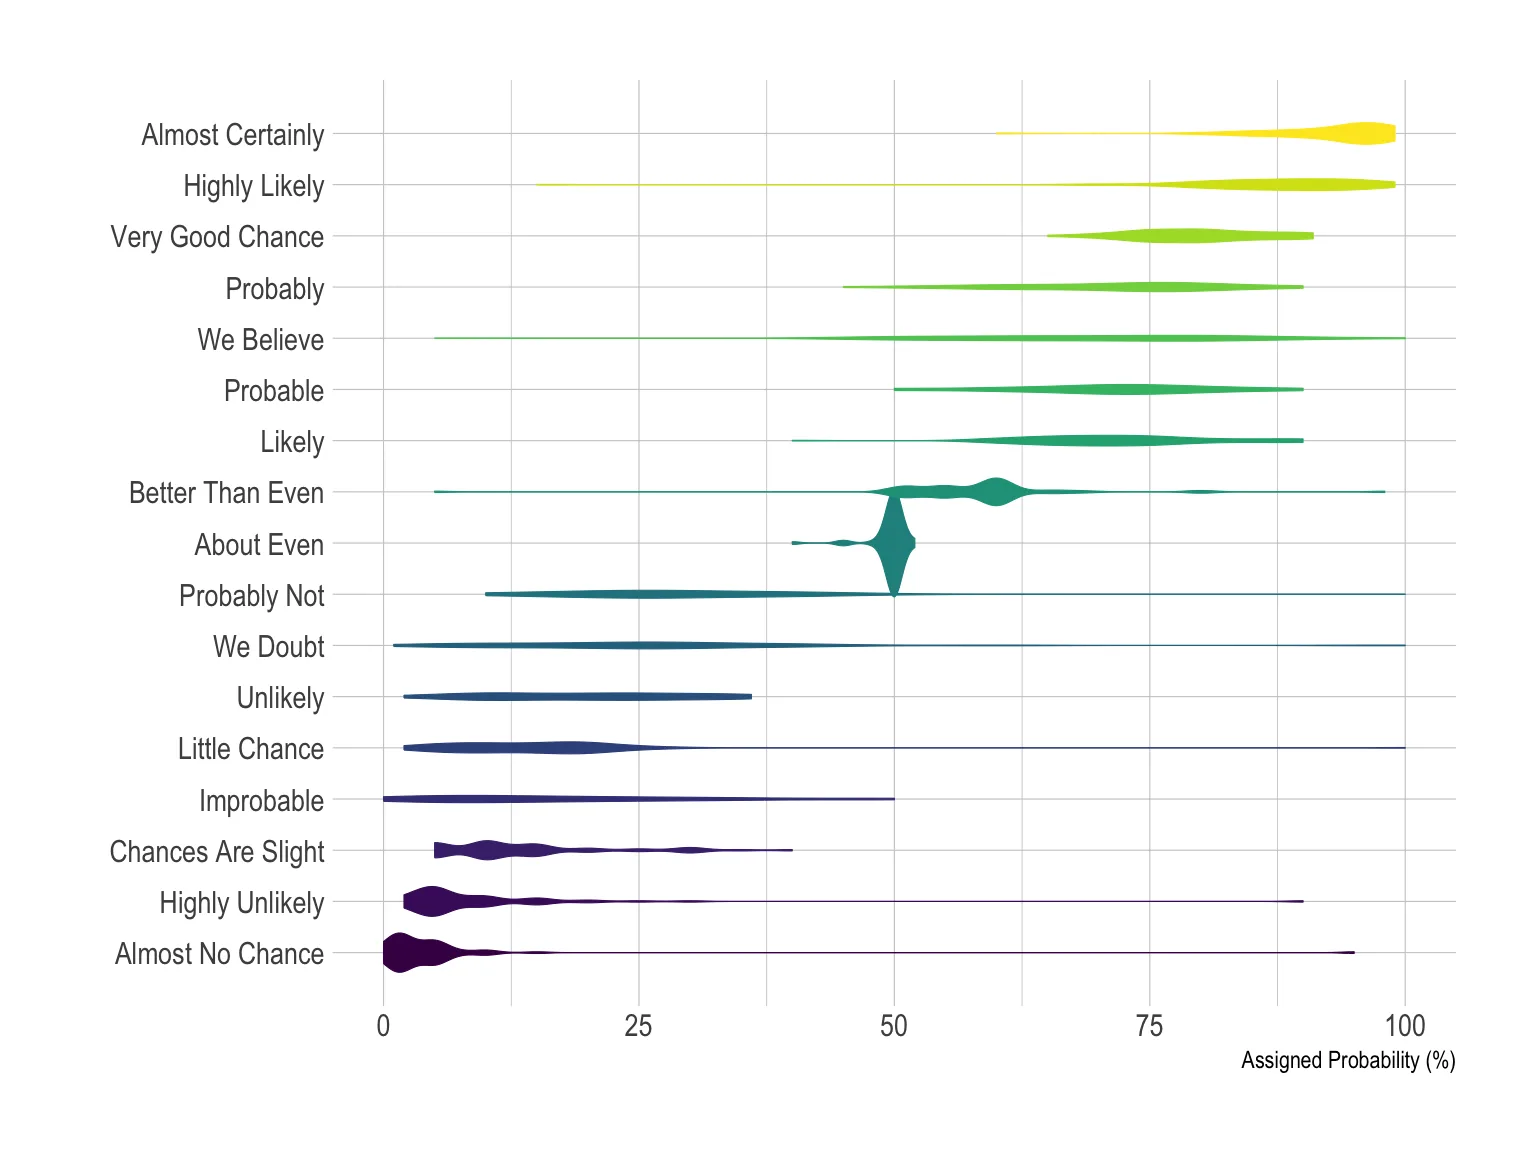
Ridgeline
Show codeHide code
library(ggridges)
data %>%
  mutate(text = fct_reorder(text, value)) %>%
  ggplot( aes(y=text, x=value,  fill=text)) +
    geom_density_ridges(alpha=0.6, bandwidth=4) +
    scale_fill_viridis(discrete=TRUE) +
    scale_color_viridis(discrete=TRUE) +
    theme_ipsum() +
    theme(
      legend.position="none",
      panel.spacing = unit(0.1, "lines"),
      strip.text.x = element_text(size = 8)
    ) +
    xlab("") +
    ylab("Assigned Probability (%)")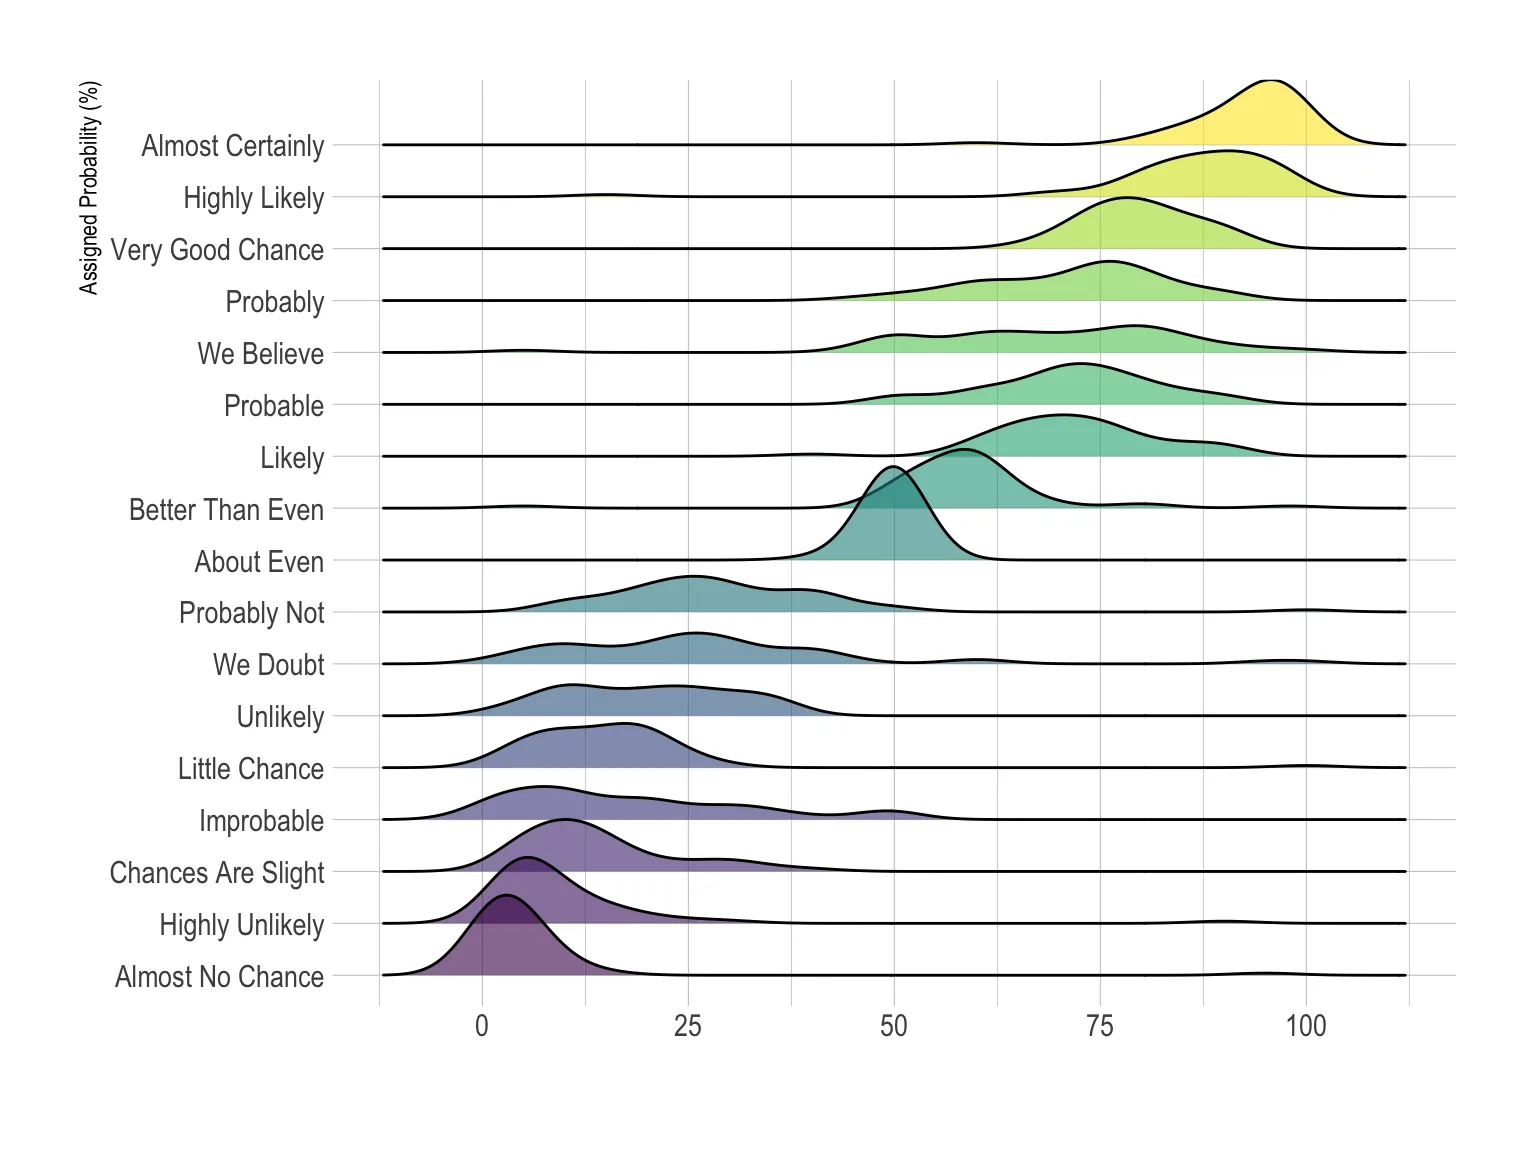
Faceting
Show codeHide code
data %>%
  mutate(text = fct_reorder(text, value)) %>%
  ggplot( aes(x=value, color=text, fill=text)) +
    geom_density(alpha=0.6) +
    scale_fill_viridis(discrete=TRUE) +
    scale_color_viridis(discrete=TRUE) +
    theme_ipsum() +
    theme(
      legend.position="none",
      panel.spacing = unit(0.1, "lines"),
      strip.text.x = element_text(size = 8)
    ) +
    xlab("") +
    ylab("Assigned Probability (%)") +
    facet_wrap(~text, scale="free_y")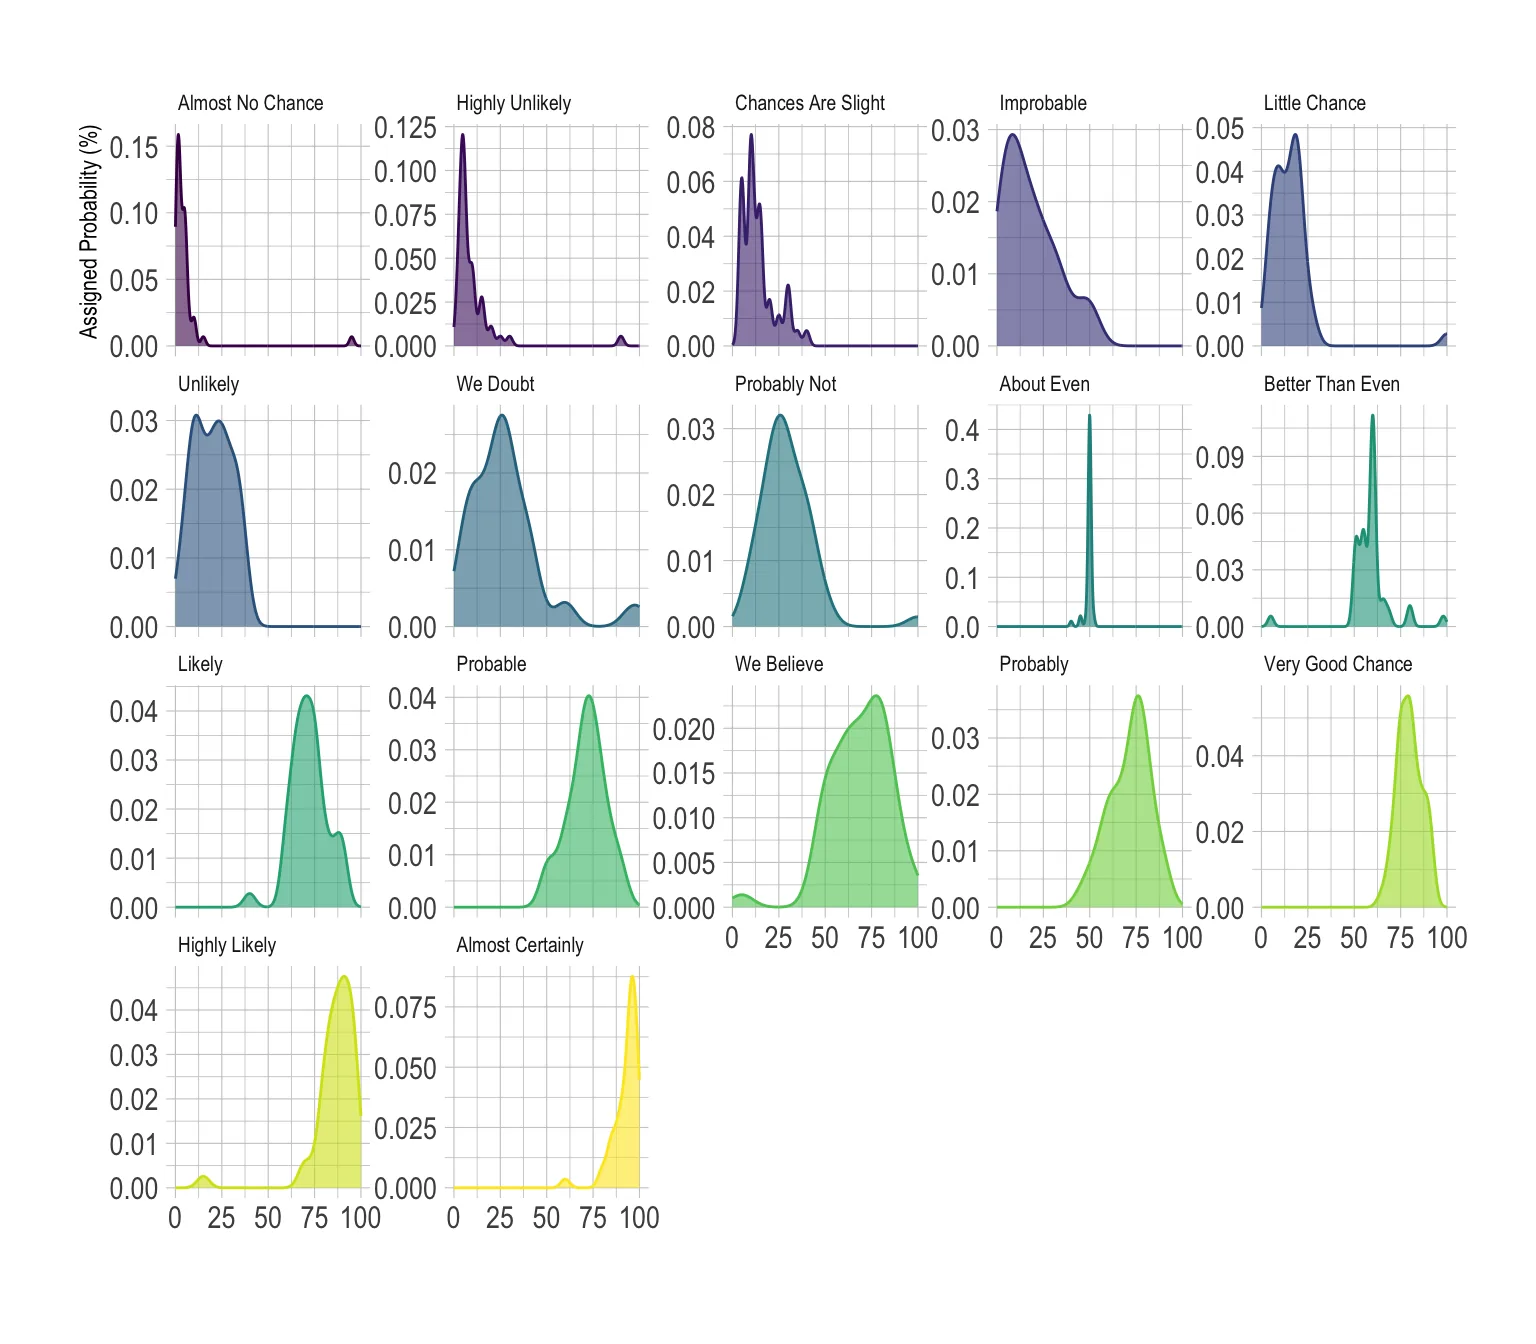
Going further
Disclaimer: This idea originally comes from a publication of the CIA which resulted in this figure. Then, Zoni Nation cleaned the reddit dataset and built graphics with R. I heavily rely on his work in this post.
Other link: